DPO(直接偏好优化)DPO (Direct Preference Optimization)
DPO (Direct Preference Optimization)
用成对的「更好 / 更差」回答直接微调模型,省掉奖励模型和强化学习。Fine-tune directly on paired better and worse answers, without a reward model or reinforcement learning.
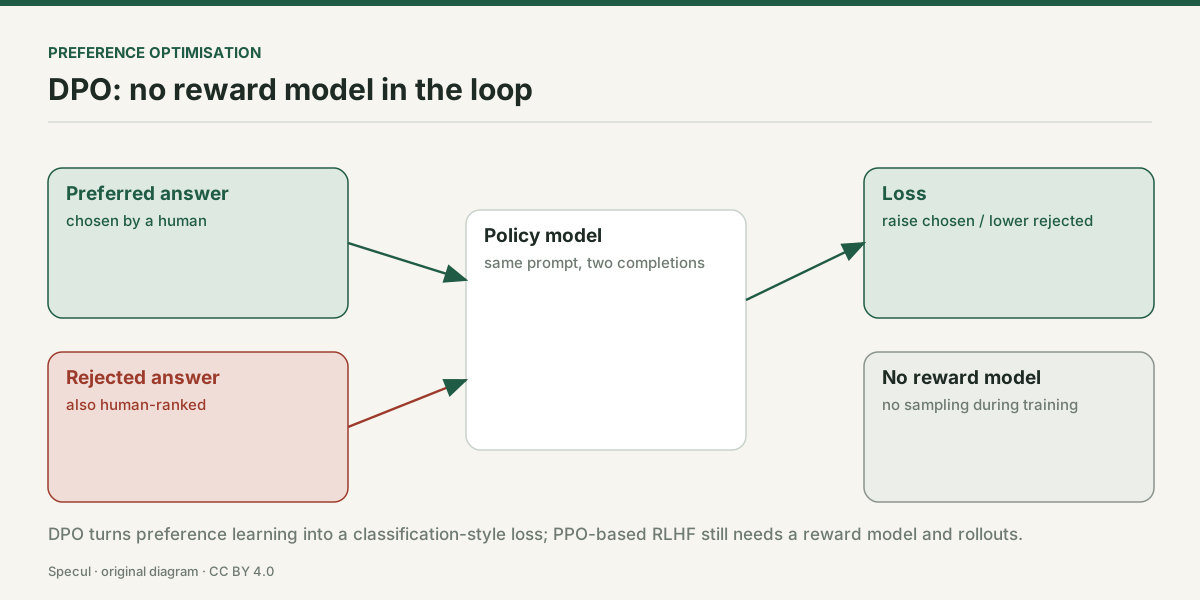
DPO 把 RLHF 的目标改写成分类损失:提高优选回答的概率、降低劣选回答的概率。
它不需要在训练中从模型采样,也不需要单独训练奖励模型。
DPO rewrites the RLHF objective as a classification loss: raise the probability of the preferred answer and lower the rejected one.
It needs neither sampling from the model during training nor a separately trained reward model.
想让模型更符合偏好但不想搭 PPO 那一套时,DPO 是更轻的选择;偏好数据的覆盖面仍然决定效果上限。When you want preference alignment without the PPO machinery, DPO is the lighter option. The coverage of preference data still caps the result.
直接偏好优化 · direct preference optimization
回到名词地图看第3站的其他 54 个词 →Back to the map: the other 54 terms in station 3 →