SFT(监督微调)SFT (Supervised Fine-Tuning)
SFT (Supervised Fine-Tuning)
解决什么问题What problem it solves
用人工写好的示范答案继续训练模型,让它学会按指令回答。Continue training on human-written demonstrations so the model learns to answer instructions.
这是什么What it is
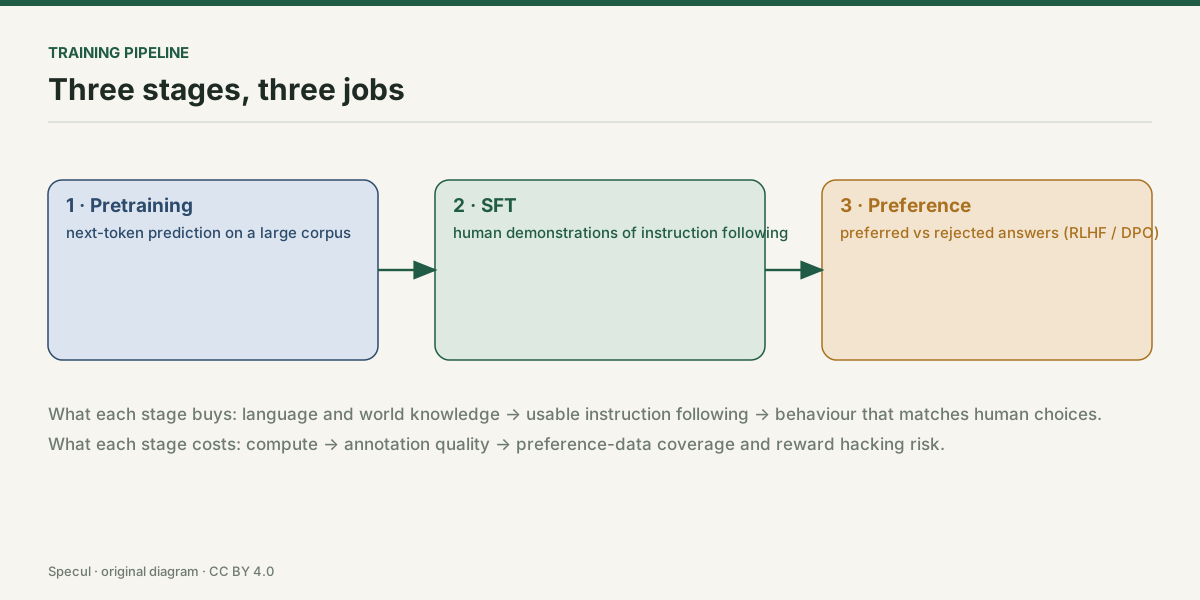
SFT 在预训练模型上做有监督学习,数据是「指令 + 期望回答」。
InstructGPT 先用标注员示范做 SFT,再用人类偏好排序做强化学习。
SFT is supervised learning on top of a pretrained model, with instruction-answer pairs.
InstructGPT first used labeler demonstrations for SFT, then human preference rankings for reinforcement learning.
为什么需要知道Why it matters
它是把基座模型变成可用助手的第一步;SFT 数据质量比数量更重要,也会把标注者的风格带进模型。It is the first step that turns a base model into a usable assistant. Data quality matters more than volume, and the annotators’ style enters the model.
别名Chinese aliases
监督微调 · 指令微调 · supervised fine-tuning
同域词条Terms in the same area
现在能做什么What you can do now
回到名词地图看第3站的其他 54 个词 →Back to the map: the other 54 terms in station 3 →