LLM-as-a-Judge(模型评审)LLM-as-a-Judge
LLM-as-a-Judge
解决什么问题What problem it solves
让一个强模型按评分标准给另一个模型的回答打分或比较。Have a strong model score or compare another model’s answers against a rubric.
这是什么What it is
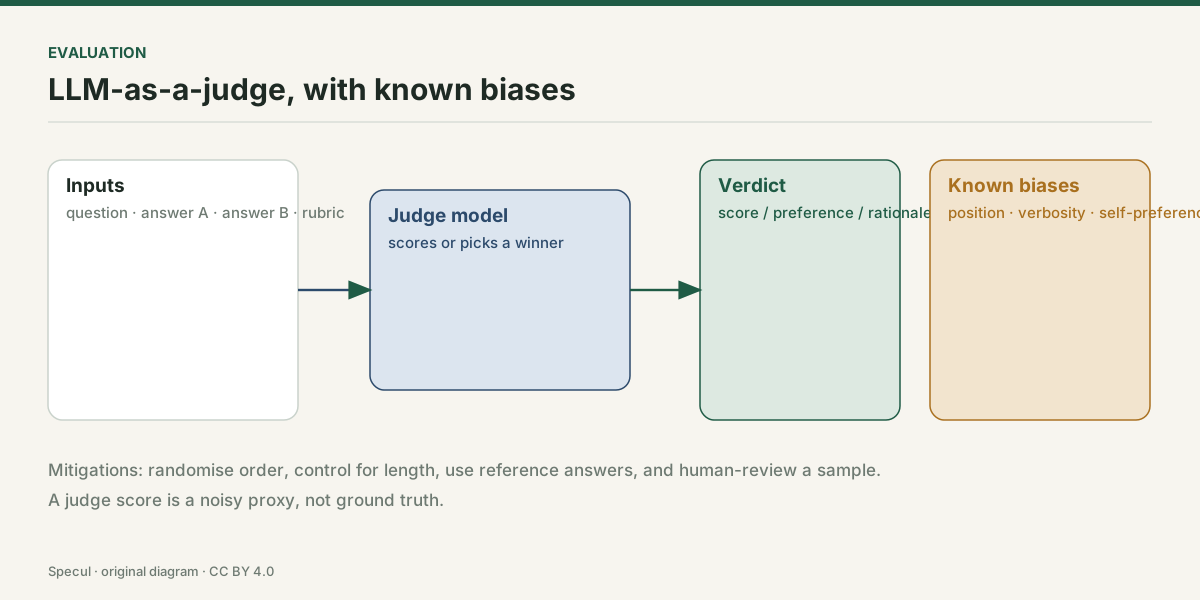
常见做法是给评审模型题目、参考答案和评分维度,让它输出分数或选择。
MT-Bench 与 Chatbot Arena 的论文系统检验了位置偏差、冗长偏差和自我偏好等问题。
A common setup gives the judge the question, a reference answer and scoring dimensions, and asks for a score or choice.
The MT-Bench and Chatbot Arena paper systematically examined position, verbosity and self-enhancement biases.
为什么需要知道Why it matters
人工评测贵且慢;模型评审能扩大规模,但必须校准偏差、抽样人工复核,不能把分数当 ground truth。Human evaluation is expensive and slow; model judging scales it up. But biases must be calibrated and sampled for human review — scores are not ground truth.
别名Chinese aliases
模型评审 · LLM judge · AI 评审
同域词条Terms in the same area