梯度下降Gradient Descent
Gradient Descent
解决什么问题What problem it solves
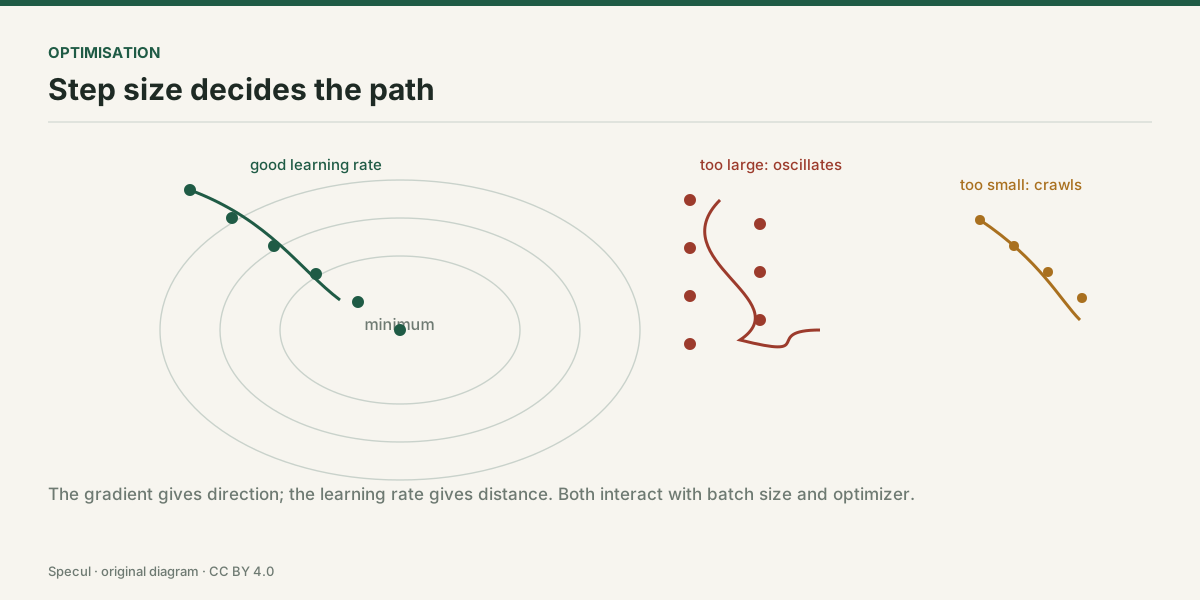
沿着梯度的反方向小步更新参数,让损失逐步下降。Update parameters in the direction opposite the gradient, in small steps, so the loss goes down.
这是什么What it is
每次用一批数据算梯度,再按学习率缩放后更新权重。
SGD、Adam、AdamW 都是它的变体,差别在如何利用历史梯度。
Each step computes a gradient on a batch and scales it by the learning rate before updating weights.
SGD, Adam and AdamW are variants that differ in how they use gradient history.
为什么需要知道Why it matters
学习率、批大小、优化器三者互相影响;同一套超参换模型或换数据常常失效。Learning rate, batch size and optimizer interact. The same hyperparameters often stop working when the model or data changes.
别名Chinese aliases
GD · SGD · 最速下降
同域词条Terms in the same area
现在能做什么What you can do now
回到名词地图看第4站的其他 46 个词 →Back to the map: the other 46 terms in station 4 →